Last updated: November 2026
Key takeaways
- World model training data is mostly video plus the actions that caused each change. Large unlabeled video teaches motion; a smaller set of aligned action or robot-state logs teaches what an agent’s moves do.
- Egocentric video shows hands, tools and objects from the actor’s own viewpoint, which is close to what a robot’s head or wrist camera sees.
- Specs decide whether clips are usable: a steady frame rate, one shared clock across sensors, recorded camera intrinsics and a fixed metadata schema.
- Once specs are right, coverage matters more than raw hours. Plan scenes, objects, tasks, embodiments and failure cases before capture starts.
- In the EU, footage of identifiable people is personal data under the GDPR. Plan consent, data minimization and de-identification before the first recording.
World model training data is the video, action and sensor record a model studies to learn how the physical world changes. It is not a labeled image set. A world model has to see cause and effect: a hand pushes, a drawer slides, a cup tips over.
This guide is for robotics, physical-AI and embodied-AI teams in the US and EU who are scoping a world model dataset. You will get the data types that matter and the specs that make clips usable. You also get a coverage plan, consent basics and the FRAMES scoping checklist.
Scoping a world model dataset now? Book a 20-minute scoping call to talk through devices, actions and coverage with our team.
What is a world model?
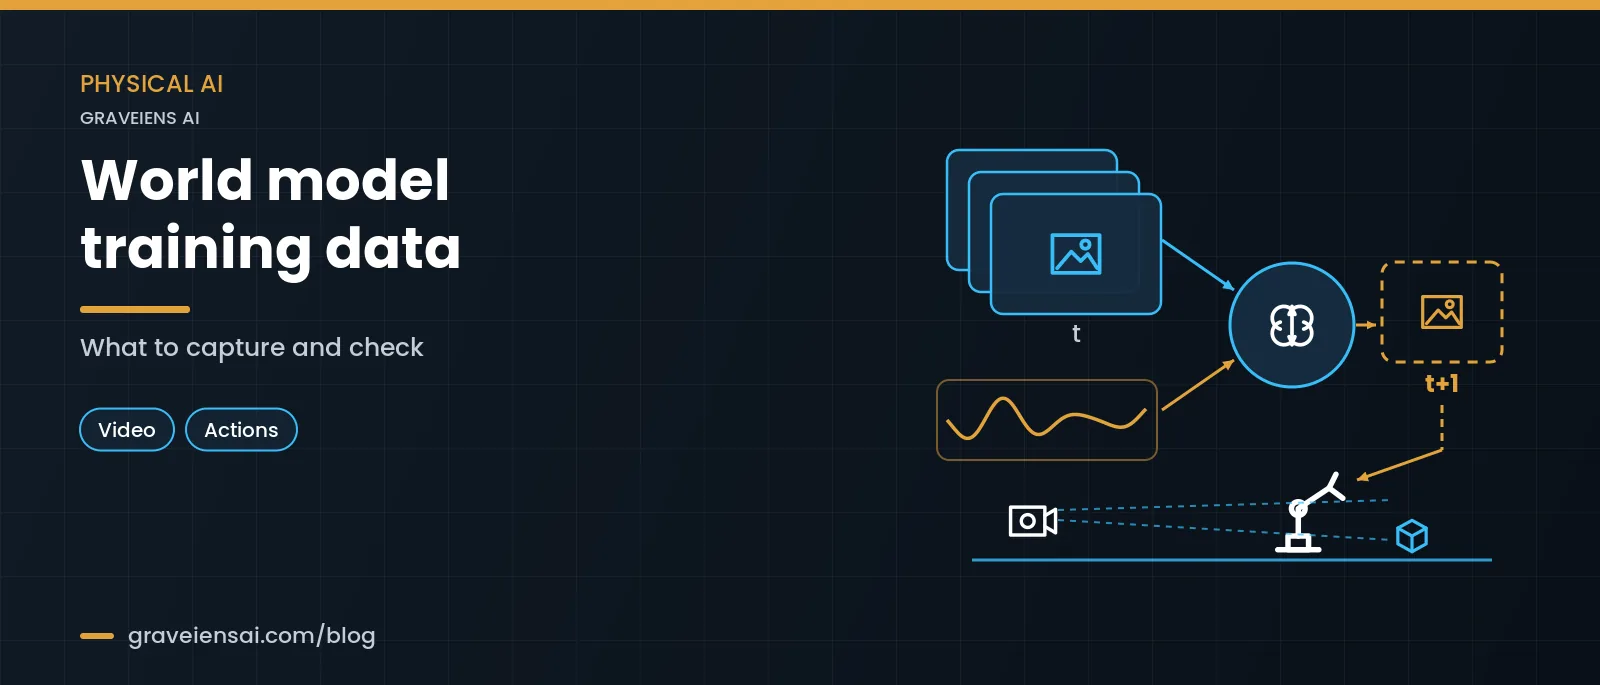
A world model is a neural network that learns how an environment changes over time, so it can predict what comes next. Video prediction models forecast future frames from past frames. Action-conditioned world models also take an action as input, so they can predict the result of a move before a robot makes it.
NVIDIA’s glossary describes world models as AI systems that understand real-world dynamics, including physics and spatio-temporal relationships. It also notes that their training data can include large-scale video, images, text, 3D data, sensor observations and sometimes actions or trajectories [1].
Three public research efforts show how this works in practice:
- NVIDIA Cosmos. The Cosmos platform paper describes world foundation models that are pretrained on video and then post-trained for camera control, robotic manipulation and driving. The team gathered about 20 million hours of raw video and extracted about 100 million clips of 2 to 60 seconds [2].
- Google DeepMind Genie 3. Genie 3 generates interactive environments from a text prompt. Users can navigate them in real time at 24 frames per second and 720p, with consistency for a few minutes. Each frame is generated in sequence, based on the world description and the user’s actions [3].
- Meta V‑JEPA 2. V‑JEPA 2 was pretrained without actions on over 1 million hours of internet video. The team then post-trained an action-conditioned version, V‑JEPA 2‑AC, on less than 62 hours of unlabeled robot video from the DROID dataset.
In short: large volumes of passive video teach a model how the world looks and moves. A much smaller, carefully aligned set of action data teaches it what an agent’s actions do.
What training data does a world model need?
Most world models need two layers of data. A large pretraining layer of varied video teaches appearance and motion. A smaller action layer pairs video with the actions, robot states or controls that caused each change. Egocentric video, teleoperation demos, multi-view rigs and simulation each fill a different gap in that action layer.
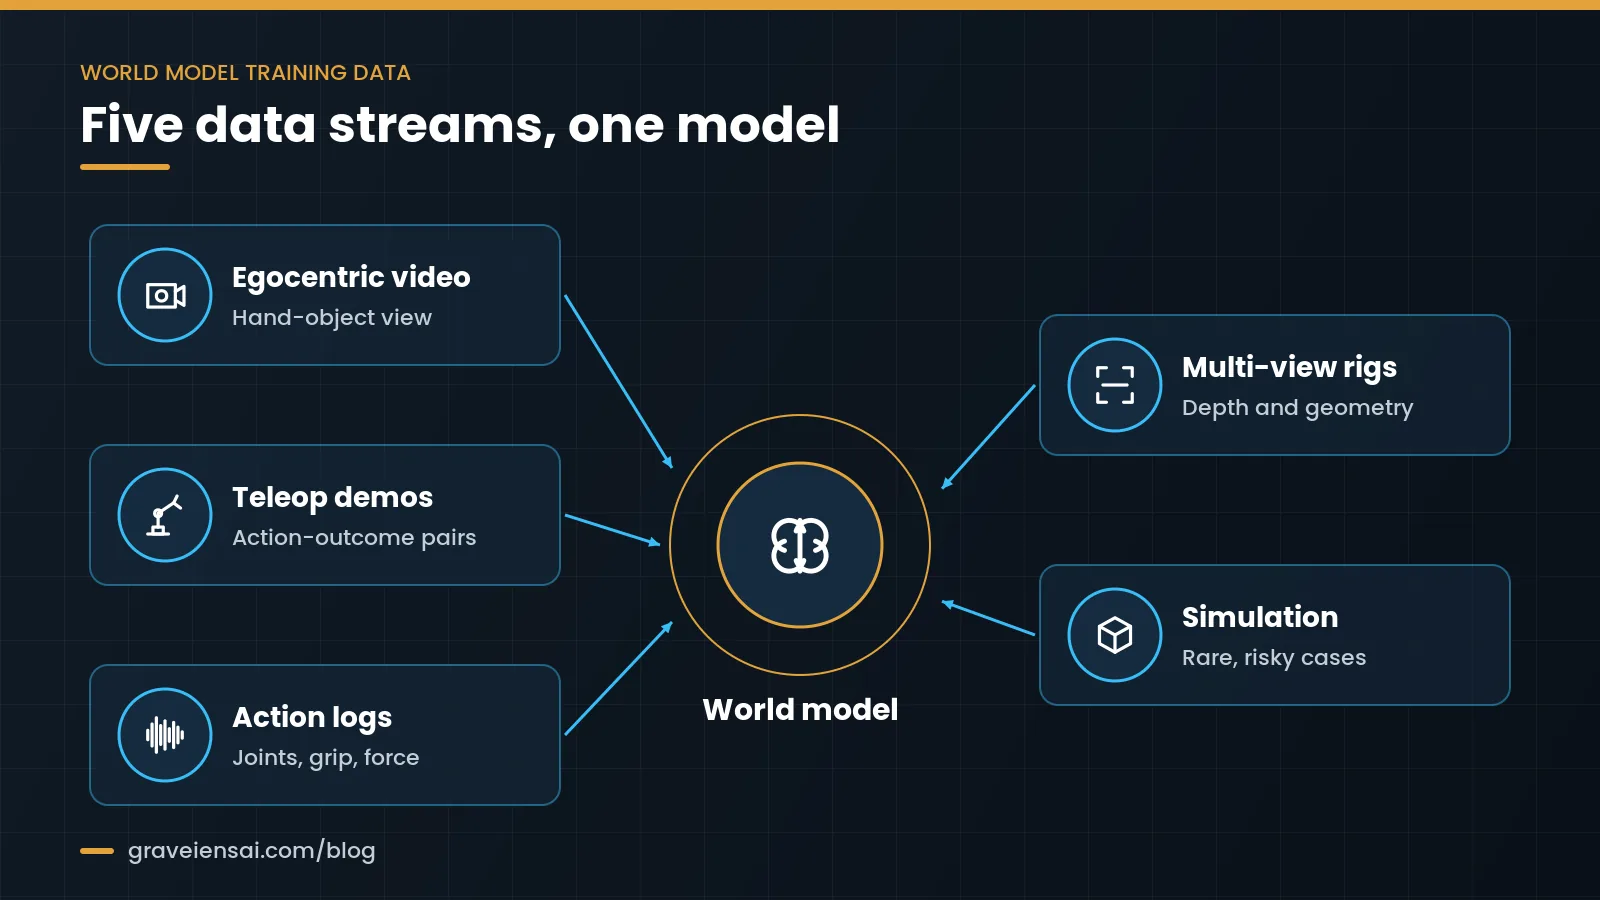
Egocentric video
Egocentric video is first-person footage from a head- or chest-mounted camera. It shows hands, tools and objects from the actor’s viewpoint. That framing is close to what a humanoid’s head camera or a wrist camera sees during manipulation.
Diversity is planned, not accidental. The Ego4D research dataset, for example, holds 3,670 hours of daily-life video from 931 camera wearers in 74 locations across 9 countries [5]. The limit is that actions are implicit: you see the hand move, but not a motor command. Teams add hand pose, step labels or narration as proxy actions.
Action and proprioception logs
Proprioception logs record what the robot did and felt. Typical streams are joint positions and velocities, gripper state, end-effector pose, force, torque and base odometry. These streams run at their own rates. They are only useful once they are aligned to video frames on a shared clock.
Teleoperation demonstrations
In teleoperation, a human operator drives the robot through a task. You get video, the exact commands and the robot’s state in one record. This is the strongest action signal you can collect. It is also the slowest to scale, because every hour needs a robot, an operator and a reset. See our teleoperation data collection services for how these sessions are run.
Multi-view and third-person video
Fixed cameras around a workspace, combined with wrist or head cameras, show the same event from several angles. When the cameras are calibrated, multi-view video gives the model geometry, depth cues and a way to reason about occlusion.
Simulation and synthetic data
Simulation gives perfect labels and safe access to rare or risky events, such as dropped objects or collisions. Its weakness is the gap between simulated and real physics and appearance. Most teams use it to fill coverage holes in world model training data, not to replace real capture. Our simulation and synthetic data services cover this layer.
What specs should world model training data meet?
Usable world model training data has a steady frame rate and timestamps from one shared clock. It also needs calibrated cameras with recorded intrinsics and action labels aligned to frames. Every clip also needs a fixed metadata record: device, scene, task, pseudonymous operator ID, consent status and QA result. Without these, clips are hard to combine or trust.
Frame rate and resolution
Capture at the rate your model trains at, or capture higher and downsample later. Never mix variable and constant frame rates without flagging it. Keep resolution fixed per device family. Cosmos’s raw pool ranged from 720p to 4K, and the team sharded clips by resolution and aspect ratio before training [2].
Time sync across sensors
Put cameras, IMUs and the robot controller on one clock. Record known offsets in the session log. Add a visible sync event, such as an LED flash, at the start of each session so QA can check alignment later.
Camera intrinsics and extrinsics
Record focal length, principal point and lens distortion for each device and each capture mode. For multi-view and wrist cameras, record extrinsics too, meaning each camera’s pose relative to the others. Recalibrate whenever a mount moves.
Action labels
Define the action space before capture. Common choices are end-effector deltas, joint targets or discrete step labels. State the units, coordinate frames and rates. For human egocentric video, use hand pose or step-level narration as proxy actions and keep the label guide versioned.
Metadata schema
- Session ID, device family, firmware and capture mode
- Scene type, location class and lighting condition
- Task name, objects used and outcome (success, failure, recovery)
- Pseudonymous participant or operator ID and consent record reference
- Calibration file version, sync offsets and QA status
How much coverage and diversity does a world model dataset need?
There is no universal hour count. Coverage should match where the model will run: the scenes, objects, tasks, lighting and embodiments it must handle, plus failures and recoveries. Plan a coverage matrix first, then fill its cells. Volume without coverage repeats the same dynamics and wastes budget.
The V‑JEPA 2 result is a useful signal here. A small action-conditioned set, under 62 hours of robot video, sat on top of a very large passive video base [4]. That pattern suggests the action layer rewards careful coverage more than raw volume.
Build the matrix from these axes:
- Environments: homes, kitchens, warehouses, retail floors, labs.
- Objects and materials: rigid, deformable, transparent, reflective, articulated.
- Task verbs: pick, place, pour, open, fold, wipe, hand over.
- Conditions: lighting, clutter and camera motion.
- Embodiments: human hands, parallel grippers, dexterous hands.
- Outcomes: success, failure and recovery, labeled as such.
Watch for redundancy as well as gaps. The Cosmos pipeline included a semantic deduplication step for this reason [2]. For a wider view of humanoid data needs, see our guide to humanoid robot training data.
How to build a world model dataset: a six-step process
In short: world model training data moves through scope, consent, capture, sync, labeling and QA, with a recapture loop when checks fail.
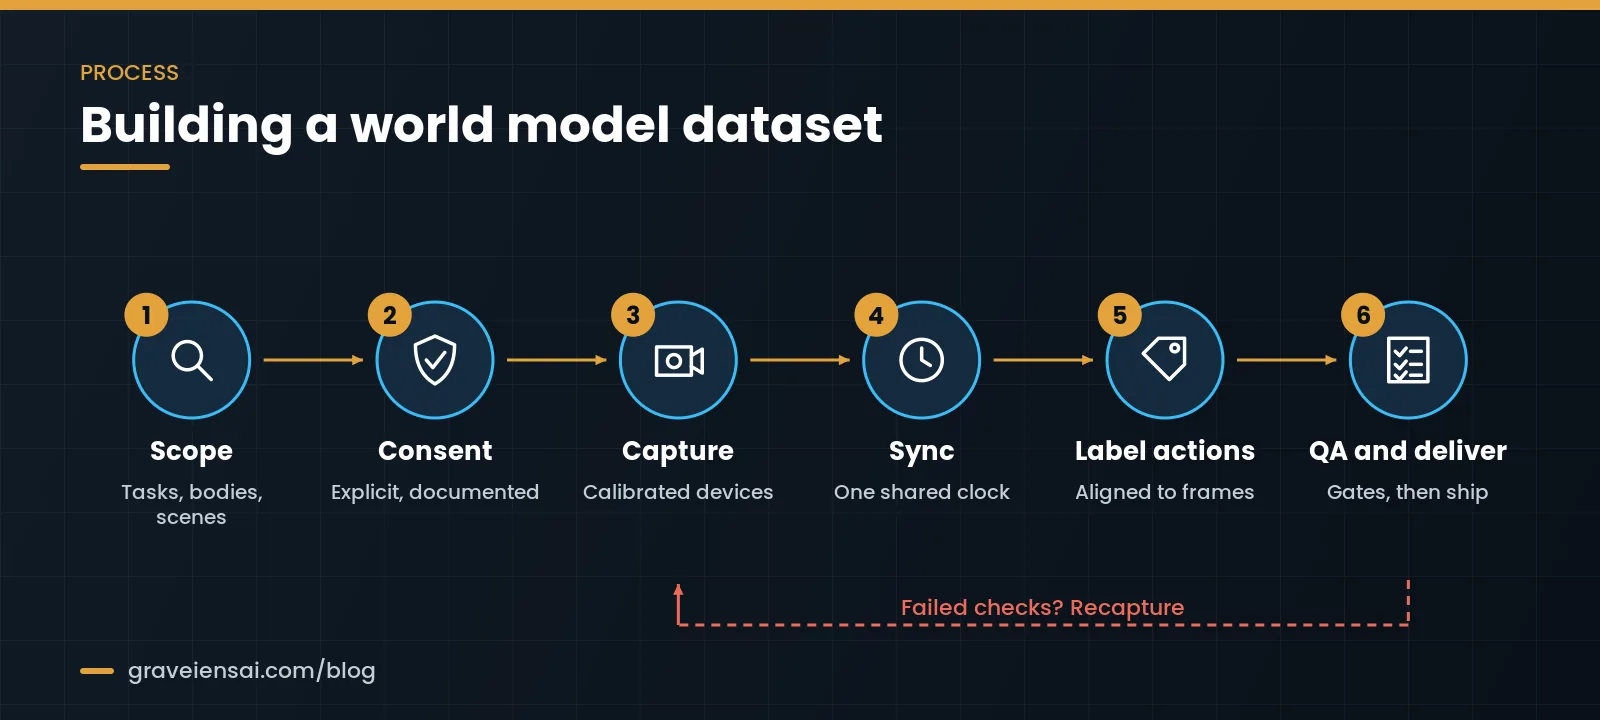
- Scope. Name the model’s job, target embodiment and deployment scenes. Turn them into a coverage matrix and an action space.
- Consent. Write participant information, consent forms and a bystander policy. In the EU, decide the legal basis and whether a data protection impact assessment is needed.
- Capture. Use calibrated devices with locked settings. Run a short pilot first and review it before scaling.
- Sync. Align video, IMU and robot logs to one clock. Check every session’s sync event and record offsets.
- Label actions. Apply the action schema: robot commands, hand pose, step labels or narration. Keep the label guide versioned.
- QA and deliver. Check specs, sync, labels, privacy redaction and metadata. Deliver in the agreed format with a manifest, and send failed sessions back for recapture.
The FRAMES checklist for scoping world model training data
FRAMES is our six-part checklist for scoping a world model dataset before any capture starts. Each letter is a decision you should write down and sign off.
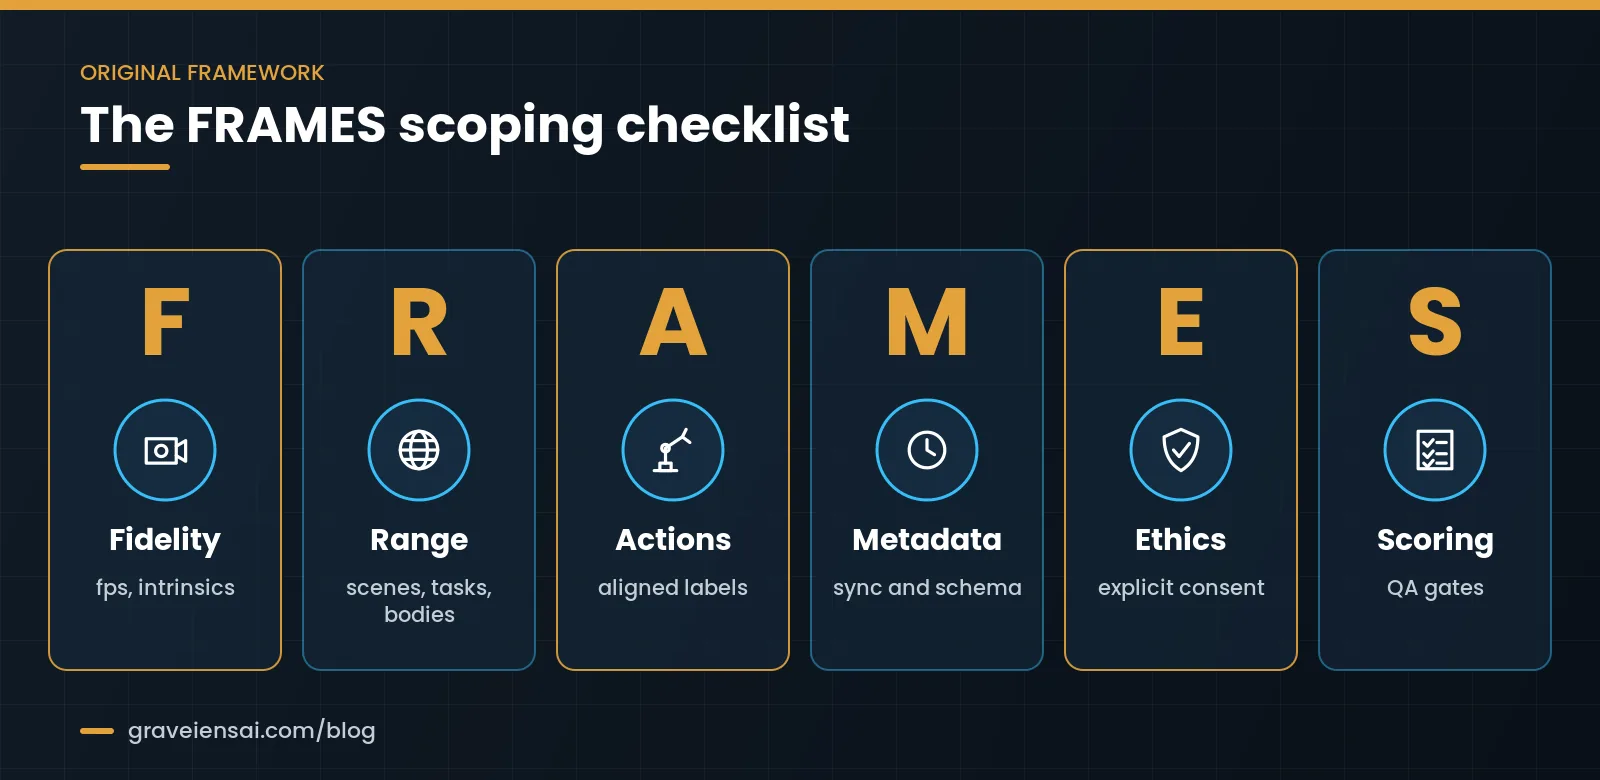
- F, Fidelity. Which devices, frame rate, resolution and field of view? Are intrinsics recorded per device and mode?
- R, Range. Which scenes, objects, task verbs, embodiments and outcomes must be covered? What is the minimum per cell?
- A, Actions. What is the action space? Robot commands, hand pose or step labels? At what rate, in which units and frames?
- M, Metadata. What is the clock source, the sync method and the fixed schema every clip must carry?
- E, Ethics. How are explicit consent, bystanders, minors, screens and documents handled? What is redacted, and who can withdraw?
- S, Scoring. What QA gates apply, what are the pass rules, and what triggers recapture?
If any letter has no written answer, the dataset is not ready to scale.
Want a second pair of eyes on your FRAMES answers? Scope a pilot billed only on approved files and test your spec on real footage first.
What drives the effort and cost of world model training data?
Effort in world model training data is driven by action alignment more than raw footage. Hours of passive egocentric video scale fairly easily. Synchronized teleoperation, multi-camera calibration, dense action labels, privacy redaction and recapture loops add most of the work. Scope these drivers before you compare quotes.
| Driver | Lower effort | Higher effort | Decide early |
|---|---|---|---|
| Data source | Single-camera egocentric video | Teleoperation with robot state logs | Which layer you need now |
| Sensor setup | One device family, fixed settings | Multi-view rigs, wrist cameras, IMUs | Calibration and sync method |
| Action labels | Clip-level task tags | Frame-aligned actions or hand pose | Action space and label rate |
| Coverage | Few scene types, common objects | Many scenes, rare objects, failures | Minimum per matrix cell |
| Privacy | Controlled sets with no bystanders | Public or shared spaces | Consent and redaction rules |
| QA depth | Spot checks on samples | Full review with recapture loop | Pass rules per gate |
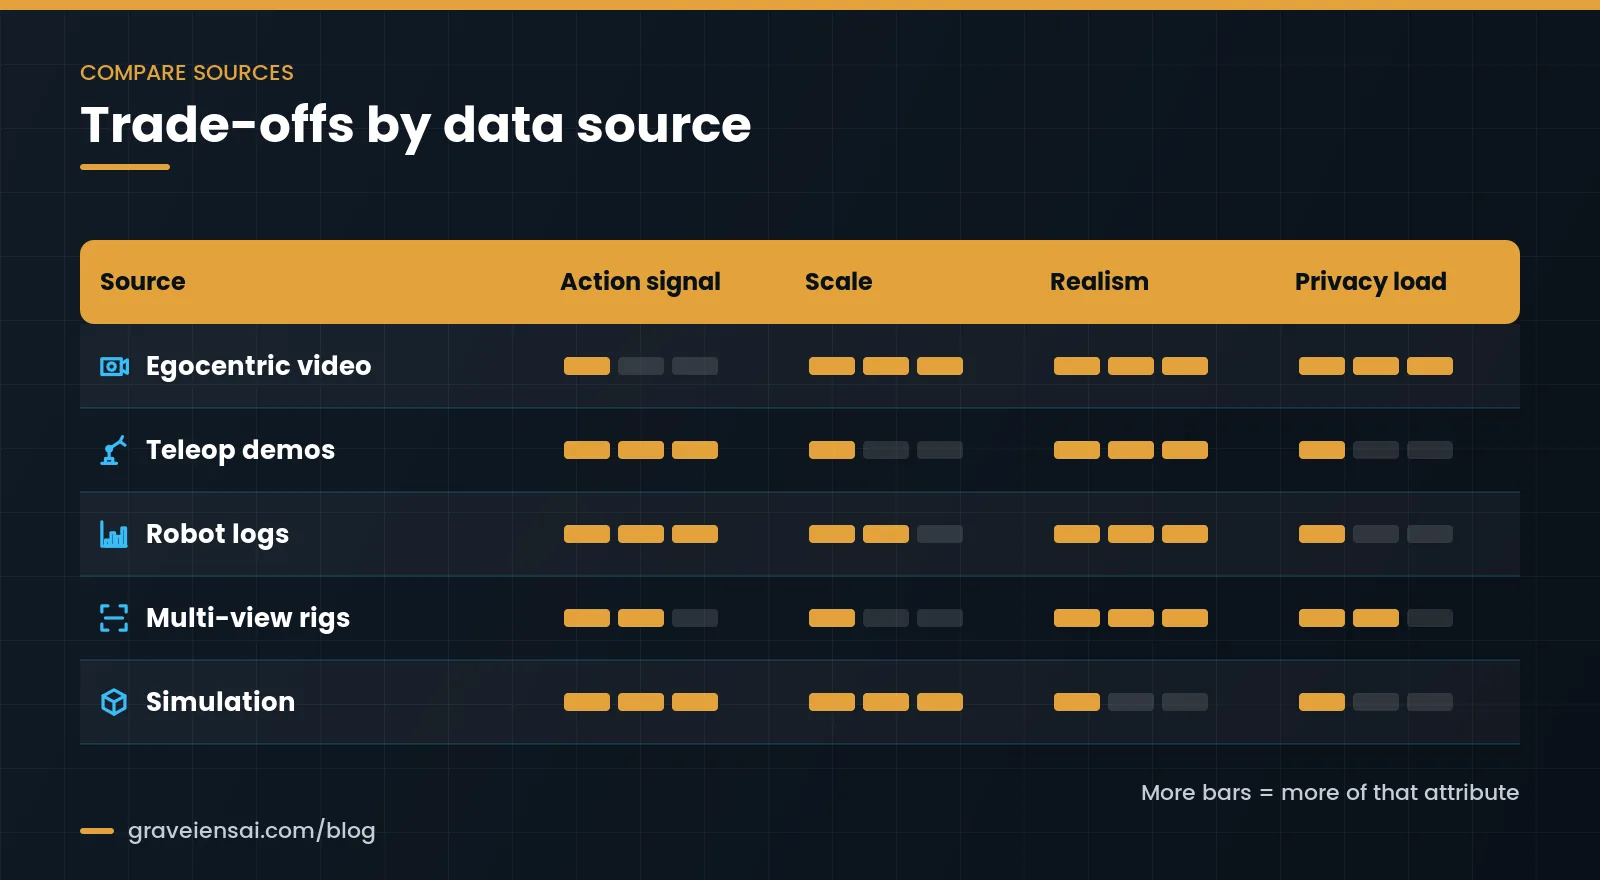
Most teams blend sources. Egocentric video adds scale and realism, teleoperation adds precise actions, and simulation adds rare events. For more on how these layers fit together, read our overview of physical AI training data for robotics.
Consent, privacy and common mistakes in world model training data
In short: treat every identifiable face, voice and home as personal data. Get explicit consent where the law expects it, and design capture to collect less.
EU capture and the GDPR
Video of identifiable people is personal data under the GDPR [6]. Article 9 prohibits processing biometric data to uniquely identify a person. Exceptions exist, such as explicit consent for specified purposes. Article 35 requires a data protection impact assessment before processing that is likely to result in high risk, especially with new technologies.
World model datasets rarely aim to identify anyone. Even so, faces, voices, screens and home interiors appear in egocentric footage. Plan data minimization, redaction and withdrawal handling up front. This is general information, not legal advice; confirm your approach with counsel.
US notes
US rules vary by state. Illinois’ Biometric Information Privacy Act lists a scan of hand or face geometry as a biometric identifier. It requires a written release before a private entity collects one [7]. Check the rules for every state where you capture.
Common mistakes that weaken world model training data
- Capturing at scale before a reviewed pilot.
- Letting devices drift to different settings or firmware mid-project.
- Logging robot state on a different clock from the cameras.
- Labeling actions without a written, versioned action schema.
- Recording only successes, so the model never sees failure or recovery.
- Treating bystanders, screens and documents as someone else’s problem.
How Graveiens AI approaches world model data collection
Graveiens AI runs an explicit-consent collection workflow. It moves from participant onboarding to recording and capture management, then metadata tagging, then QA. Our catalogue includes 150,000+ egocentric videos across seven device families. Learn more about our egocentric video data collection service.
Pilots follow a pay-for-approved-deliverables model: you are billed only on files you approve. Graveiens AI is ISO 9001 certified. For teleoperation setups, multi-view rigs, action schemas and simulation layers, we scope this with you against your FRAMES answers. If you are comparing partners, our guide to choosing an egocentric data collection vendor lists the questions to ask.
FAQ: world model training data
What is world model training data?
World model training data is the video, sensor and action record a model uses to learn how an environment changes over time. It usually combines a large layer of passive video with a smaller layer of video paired with actions or robot states. Together, these teach the model both how the world moves and what an agent’s actions change.
How is world model training data different from robot policy data?
A policy learns which action to take. A world model learns what happens after an action. Policy data needs demonstrations of good behavior. World model training data benefits from a wider spread of actions and outcomes, including failures and recoveries. The model must predict consequences, not copy an expert.
Can egocentric human video help train a robot world model?
Yes, as one layer. Egocentric video shows hands, tools and objects from a viewpoint close to a robot’s head or wrist camera, and it scales well. It lacks motor commands, so teams add proxy actions such as hand pose or step labels. Many teams pair it with a smaller set of robot or teleoperation data.
How many hours of video does a world model need?
No single number applies. V‑JEPA 2, for example, used over 1 million hours of internet video for pretraining. Its action-conditioned post-training used under 62 hours of robot video. Set your target from a coverage matrix of scenes, tasks and embodiments, then size each cell.
What frame rate should world model training video use?
Use the frame rate your model trains at, or capture higher and downsample. Keep it constant within a device family and record it in metadata. For fast manipulation, a higher rate helps capture contact events. Whatever you choose, align action logs to the same timeline using one shared clock.
Is synthetic data enough to train a world model?
Usually not on its own. Simulation gives perfect labels and safe access to rare events, but simulated physics and visuals differ from the real world. Most teams use synthetic data to fill coverage gaps and stress-test edge cases. Real egocentric and robot data anchors the model in real dynamics.
Do I need consent to collect egocentric video in the EU?
You need a lawful basis under the GDPR for any personal data, and footage of identifiable people is personal data. Where biometric data is processed to identify someone, Article 9 applies and explicit consent is a common basis. Many teams use explicit, documented consent for all participants. Confirm your approach with counsel.
Ready to scope your world model dataset?
Share your target tasks, embodiment and deployment scenes. We will map them to the FRAMES checklist and propose a pilot. Request a sample dataset or book a 20-minute scoping call.
Sources
- NVIDIA Glossary: What Is a World Model?
- NVIDIA et al., Cosmos World Foundation Model Platform for Physical AI (arXiv:2501.03575)
- Google DeepMind, Genie 3: A new frontier for world models
- Assran et al., V‑JEPA 2: Self-Supervised Video Models Enable Understanding, Prediction and Planning (arXiv:2506.09985)
- Grauman et al., Ego4D: Around the World in 3,000 Hours of Egocentric Video (arXiv:2110.07058)
- Regulation (EU) 2016/679, General Data Protection Regulation, EUR-Lex
- Illinois General Assembly, Biometric Information Privacy Act (740 ILCS 14)
About the author
Graveiens AI Editorial Team. The Graveiens AI Editorial Team writes about data collection, annotation and quality review for teams building speech, language and physical-AI models. The team draws on day-to-day work running consent-based capture and QA for AI training datasets.

Jitendra Choubay is the CEO & Founder of Graveiens AI, leading a human-in-the-loop data services team that helps AI builders with data collection, annotation, consent-backed voice data, transcription and LLM fine-tuning. He writes on building better, ethically sourced AI training data.
Get the next Graveiens AI article
Expert notes on AI data, annotation, LLMs and eLearning — no spam, unsubscribe anytime.
Need AI Development? Data Annotation? eLearning?
Talk to Graveiens AI about data collection, annotation, voice data, RLHF/SFT, LLM evaluation and AI training data — invoiced only on approved work.
Contact Graveiens AI