Last updated: October 2026
Key takeaways
- Knowing how to collect teleoperation data starts before any session: write the robot and task brief, then agree what a successful episode looks like.
- A pilot should answer one question: can this rig, these operators and this QA process produce episodes your policy can train on?
- Log more than video. Joint states, gripper commands, timestamps and episode outcomes decide whether demonstrations are usable.
- Size the pilot by the decision it must support, not by the size of the eventual dataset.
- Close every pilot with a written go/no-go review against the acceptance criteria you set at the start.
Robot time is expensive, and a teleoperation campaign that starts without a clear spec usually produces episodes nobody can train on. This playbook is for robotics, ML and program leads who already know what teleoperation is and now need to run a first data pilot. If you need the basics first, our teleoperation explainer covers definitions, control modes and rig types. Here you get a five-phase plan for how to collect teleoperation data in a pilot, a sample brief, a logging spec, a session-day runbook, a sizing method and a go/no-go scorecard.
Ready to plan yours? Scope a pilot billed only on approved files.
How do you collect teleoperation data for a robot learning pilot?
To collect teleoperation data, a trained operator drives the robot (or a matched rig) through a defined task while the system records synchronized camera streams, joint states and commands for every episode. Each episode is then checked against written acceptance criteria. A pilot runs this loop at small scale to prove the rig, operators and QA work before you commit to volume.
In short: a pilot is a test of your data pipeline, not a small version of your final dataset. Treat it as an experiment with a hypothesis, a budget and a decision date.
What should a teleoperation pilot prove?
A teleoperation pilot should prove three things: that operators can complete the task reliably on the chosen rig, that every episode is logged in a format your training code can load, and that QA can separate good episodes from bad ones using criteria everyone agreed in advance. If any of the three fails, scaling only multiplies the problem.
Write the hypothesis down. For example: “Two trained operators can produce accepted pick-and-place episodes on our arm at a steady rate, with every episode carrying synchronized wrist and overhead video, joint states and an outcome label.” A pilot with a stated hypothesis ends with a clear answer. A pilot without one ends with a folder of files.
The five phases of a teleoperation data pilot
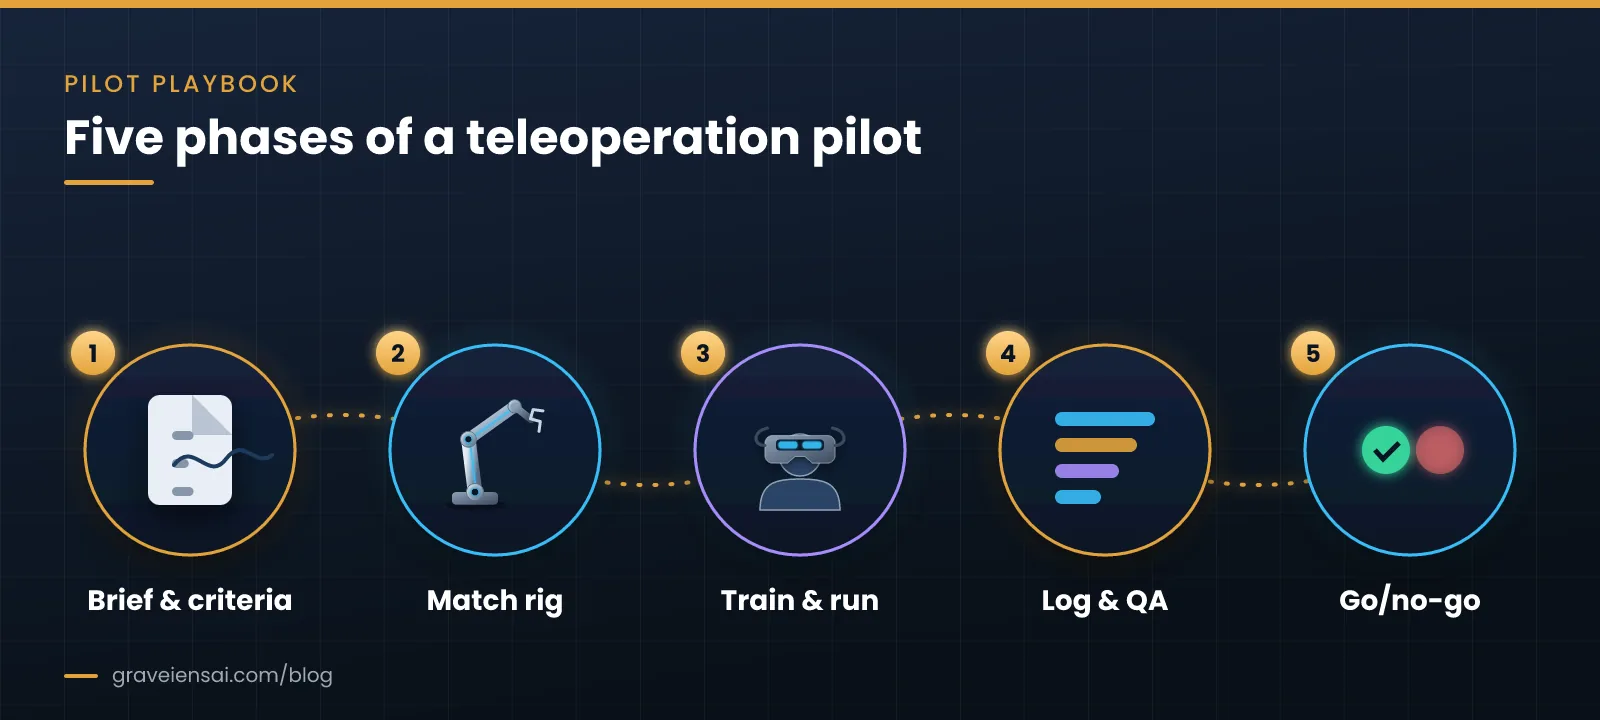
Phase 1: Write the brief and the acceptance criteria
The brief names the robot platform (make, model, degrees of freedom, end effector), the task list, the environment, safety limits and the target cycle time. Add the acceptance criteria in the same document: what counts as task success, which failures are allowed within an episode (a regrasp, say), and which ones void it (a collision, a dropped object, a missed step).
Agree the criteria before the first session. Criteria written after footage exists invite disputes, because everyone is now judging data they already paid for.
Phase 2: Match the rig to the robot and the task
Most pilots choose between a leader-follower arm pair and VR-based control. Leader-follower setups such as the open-source ALOHA system suit fine bimanual manipulation, because the operator feels the motion through a matching arm. VR-based systems such as Open-TeleVision stream the robot’s camera view to a headset and suit humanoid platforms and longer tasks. Our guide to teleoperation types compares the options in depth.
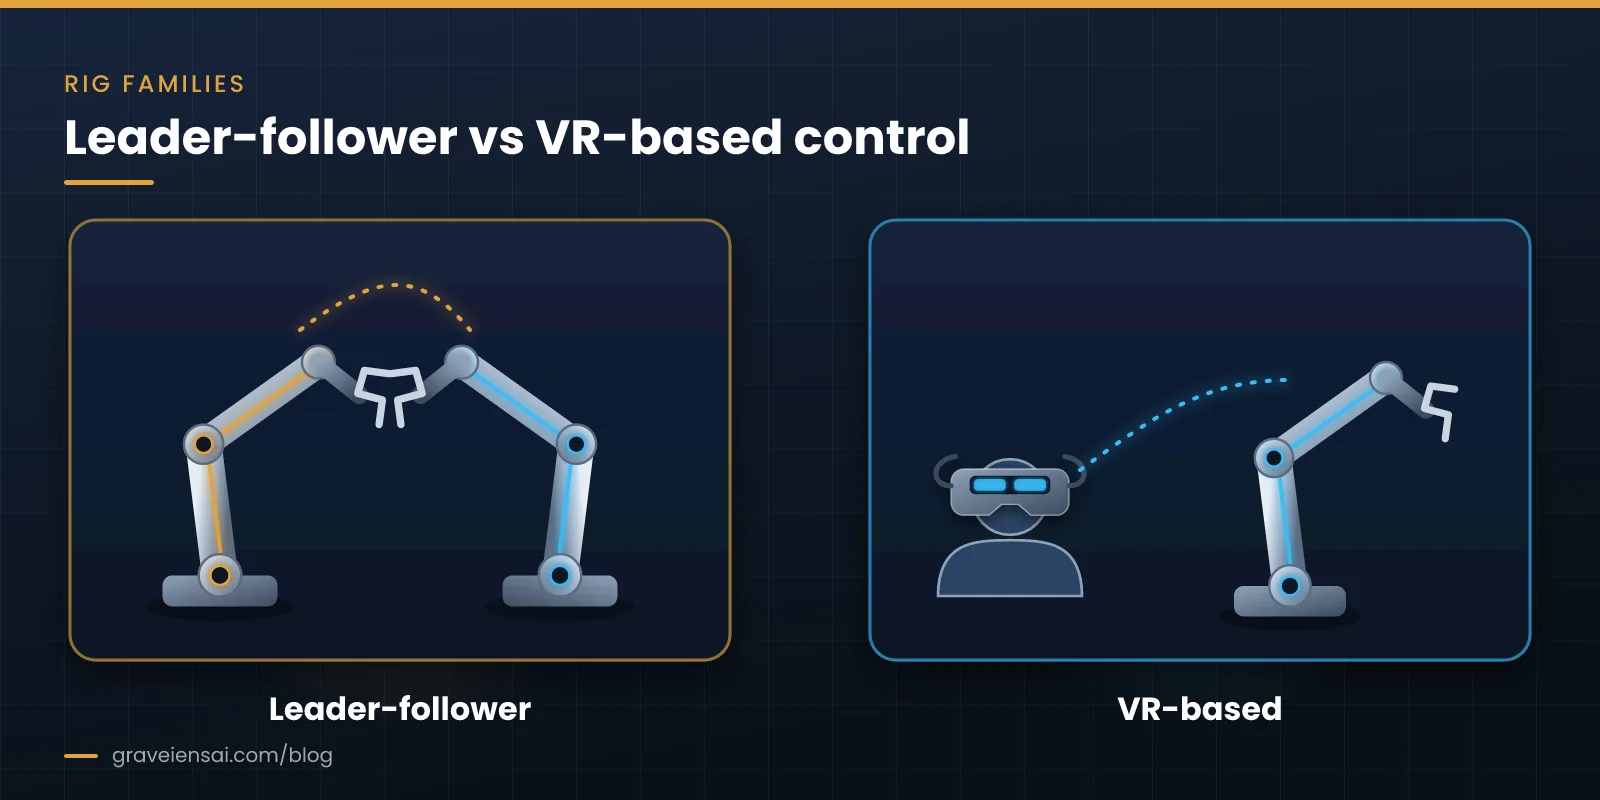
For the pilot, the question is narrower: which rig lets an operator finish your task cleanly at least most of the time? If you cannot decide, run a few sessions on each and compare acceptance rates.
Phase 3: Train operators and run supervised sessions
Operator skill drives data quality. Plan practice sessions that are recorded but excluded from the dataset, then supervised sessions where a lead flags bad episodes in real time. Rotate at least two operators so you can see whether the data reflects the task or one person’s habits.
Phase 4: Log the right signals and QA every episode
Decide the logging spec before capture. The table below is a practical minimum for most manipulation pilots.
| Signal | Why it matters | What to specify |
|---|---|---|
| Camera streams (wrist, overhead) | Policies learn from what the robot sees | Resolution, frame rate, camera IDs and mounting |
| Joint states and commands | The action labels your policy imitates | Rate, units and joint order |
| Gripper or hand state | Grasp timing is often where policies fail | Open/close values or finger positions |
| Timestamps on one clock | Misaligned streams break action-observation pairs | Clock source and allowed drift |
| Episode metadata | Lets you filter and rebalance later | Task ID, operator ID, environment, outcome, failure reason |
QA then checks each episode against the acceptance criteria and records a reason for every rejection. Rejection reasons are the most useful output of a pilot, because each one points to a spec, rig or training change.
Phase 5: Deliver, review and decide
Deliver accepted episodes in the format your training stack already loads, together with the rejection log. Then hold a go/no-go review against the hypothesis from the start of the pilot.
A sample teleoperation pilot brief
A one-page brief is enough for most pilots. Fill in every field before the first vendor or internal planning call; blanks are where scope creep starts.
| Field | Example entry |
|---|---|
| Hypothesis | Two operators can produce accepted pick-and-place episodes at a steady rate on our arm |
| Platform | Arm model, end effector, control interface and firmware version, locked for the pilot |
| Tasks | Three tasks, each with numbered steps and allowed object positions |
| Acceptance criteria | Task complete, no collision, no dropped object, all streams present and in sync |
| Logging spec | Streams, rates, clock source, file format and episode metadata fields |
| Size and stop rule | Fixed batch per task; stop and review if acceptance stays low after early sessions |
| Decision date | The day the go/no-go review happens, with named attendees |
Session-day runbook
Most lost episodes trace back to something that could have been checked before the first recording of the day. A short runbook keeps sessions consistent across operators and days.
- Before the session: confirm calibration files are current, check clock sync across cameras and robot, test the emergency stop, and record a short test episode.
- During the session: the lead logs task ID and operator ID per episode, flags failures with a reason, and pauses for breaks before fatigue shows in the data.
- After the session: copy files to two locations, run an automated check for missing streams and dropped frames, and file the day’s rejection reasons.
How many episodes should a teleoperation pilot include?
A teleoperation pilot should include enough episodes to support a decision, not to train a production policy. Most teams size it so they can measure acceptance rate per task and per operator, and run one quick training sanity check. That usually means a small, fixed batch per task, with a stop rule if the acceptance rate stays low after the first sessions.
Three questions set the number. How many tasks are in scope? How many operators do you need to compare? And does your ML team want to train a quick baseline on pilot data? Published systems show that small, clean demonstration sets can be informative: the ALOHA authors trained fine bimanual skills from real demonstrations collected with a low-cost teleoperation interface.
The PILOT readiness check
Score each item from 1 to 5 before the first session. Anything below 3 is a reason to fix the plan, not to start capturing.
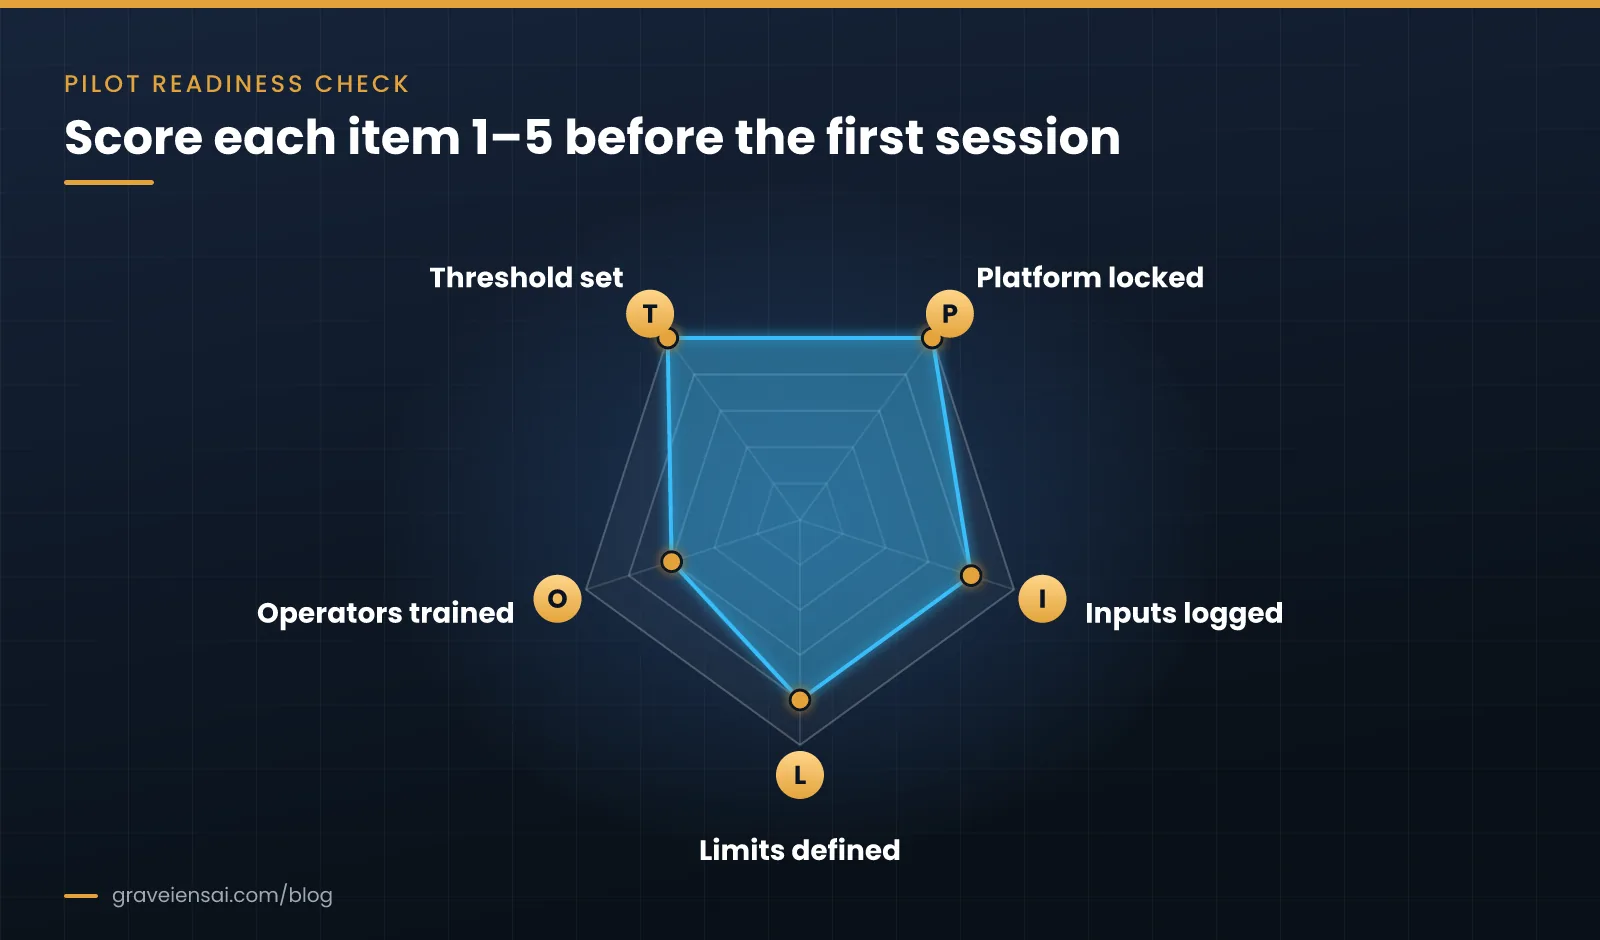
- P: Platform locked. The robot model, end effector and control interface will not change during the pilot.
- I: Inputs logged. The logging spec (streams, rates, clock, metadata) is written and tested on a dry run.
- L: Limits defined. Acceptance criteria, safety limits and stop rules are agreed in writing.
- O: Operators trained. At least two operators have finished practice sessions on the chosen rig.
- T: Threshold set. The go/no-go threshold (for example, a target acceptance rate and a passing baseline check) is written down.
Want the worksheet version? Ask us for the PILOT readiness worksheet and we will send the template our team uses on scoping calls.
What drives the effort and cost of a teleoperation pilot?
Effort in a teleoperation pilot is driven by robot access, rig build or calibration, operator training time, task complexity, the logging spec and QA depth. The biggest swing factor is usually hardware: sessions on your own robot are limited by its availability, while a matched rig can run in parallel but needs calibration against your platform.
- Robot access. Shared lab robots limit session hours per week.
- Rig work. Building, calibrating or adapting a leader arm or VR interface.
- Task complexity. Long-horizon or bimanual tasks need more practice and produce more rejects.
- Logging and sync. More streams and tighter sync tolerances add setup and checking time.
- QA depth. Frame-level review costs more than outcome-only review.
Mistakes that sink a teleoperation pilot
- No written hypothesis. Without one, nobody can say whether the pilot passed.
- Changing the platform mid-pilot. A new gripper or controller resets operator learning and invalidates comparisons.
- Logging video only. Without joint states and commands on the same clock, demonstrations cannot be used for imitation learning.
- Keeping practice runs in the dataset. Early sessions teach operators; they rarely teach policies.
- Skipping rejection reasons. A reject count tells you little; a reject reason tells you what to fix.
- Treating operator consent as an afterthought. Sessions record people too: their movements and often their faces or voices. Use the same explicit-consent process as any human-data collection.
Teleoperation is one input among several. For how demonstrations combine with egocentric video and simulation, see our guide to humanoid robot training data and the physical AI training data pillar guide.
How Graveiens AI runs teleoperation pilots
Graveiens AI handles operator recruitment, training, supervised sessions and delivery for teleoperation data services, with leader-follower arms, bimanual rigs or VR-based control matched to the client’s platform and budget. Every engagement follows our explicit-consent workflow (participant onboarding, recording and capture management, metadata tagging, QA), and clients are invoiced only for approved deliverables. Graveiens AI is ISO 9001 certified.
Teleoperation is a newer offering for us, and we are onboarding a small number of pilot partners rather than presenting it as a high-volume service. Teams that also need human task diversity can pair a pilot with egocentric video data collection.
Frequently asked questions
How long does a teleoperation data pilot take?
It depends on robot access, rig readiness and the number of tasks. Most of the calendar time goes into the brief, rig setup and operator practice rather than the recorded sessions. Plan the pilot around a fixed decision date and a stop rule, so it ends with a go/no-go call instead of drifting into open-ended collection.
What data should be logged in each teleoperation episode?
At minimum: synchronized camera streams, joint states and commands, gripper or hand state, timestamps from one clock, and episode metadata such as task, operator, environment, outcome and failure reason. Agree rates, units and formats before capture so the episodes load directly into your training pipeline.
Who should define the acceptance criteria?
The robotics or ML team that will train on the data should define them, with the data partner confirming they are measurable in QA. Criteria should cover task success, allowed recoveries, disqualifying events and sync tolerances, and they should be signed off before the first recorded session.
Should we use our own robot or a matched rig for the pilot?
Your own robot gives exact embodiment but ties up hardware time. A matched rig can run in parallel but needs calibration and carries some transfer risk. Many teams run the pilot on their own platform to validate the spec, then decide whether matched rigs make sense for scale.
What should a teleoperation pilot brief include?
A hypothesis, the locked platform details, numbered tasks, acceptance criteria, the logging spec, the pilot size with a stop rule, and a decision date. One page is usually enough; the point is that every field is filled in before the first session.
How do we know a teleoperation pilot succeeded?
Compare results with the hypothesis and threshold you wrote at the start: acceptance rate per task and operator, logging completeness, and whether a quick baseline trains on the pilot data. Clear rejection reasons and a stable acceptance rate are good signs that the pipeline is ready to scale.
Is consent needed from teleoperators?
Yes. Teleoperation sessions record people as well as robots, often including video of the operator and motion data. Collect explicit, documented consent covering AI-training use, retention and withdrawal, and keep consent records linked to the episodes, as you would for any human-data collection.
Scope your teleoperation pilot
Knowing how to collect teleoperation data starts with a brief, a logging spec and acceptance criteria. Send us your platform and task list and we will help you shape a pilot billed only on approved deliverables. See teleoperation data services or book a 20-minute scoping call.
Sources
- Zhao, T. Z., Kumar, V., Levine, S., Finn, C. “Learning Fine-Grained Bimanual Manipulation with Low-Cost Hardware.” arXiv:2304.13705. arxiv.org/abs/2304.13705
- Aldaco, J. et al. “ALOHA 2: An Enhanced Low-Cost Hardware for Bimanual Teleoperation.” arXiv:2405.02292. arxiv.org/abs/2405.02292
- Cheng, X. et al. “Open-TeleVision: Teleoperation with Immersive Active Visual Feedback.” arXiv:2407.01512. arxiv.org/abs/2407.01512
About the author
Graveiens AI Editorial Team. The team writes from day-to-day work running consent-backed data programs for AI and robotics teams, including teleoperated demonstrations, first-person video capture and annotation.
Jitendra Choubay is the CEO & Founder of Graveiens AI, leading a human-in-the-loop data services team that helps AI builders with data collection, annotation, consent-backed voice data, transcription and LLM fine-tuning. He writes on building better, ethically sourced AI training data.
Get the next Graveiens AI article
Expert notes on AI data, annotation, LLMs and eLearning — no spam, unsubscribe anytime.
Need AI Development? Data Annotation? eLearning?
Talk to Graveiens AI about data collection, annotation, voice data, RLHF/SFT, LLM evaluation and AI training data — invoiced only on approved work.
Contact Graveiens AI