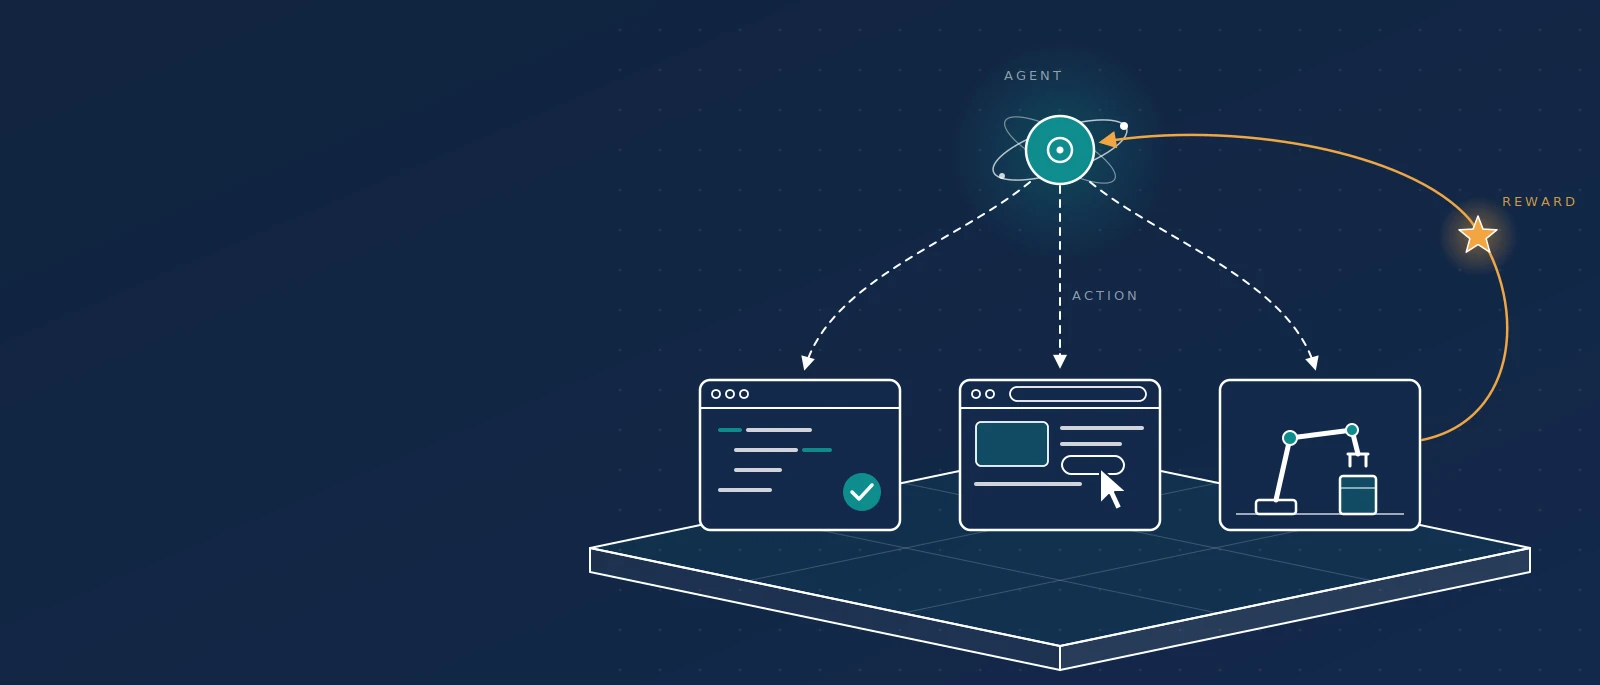
RL environments are interactive, simulated workspaces where an AI agent takes actions, sees what happens, and receives a reward score, so it learns multistep behavior through practice instead of by copying examples. For robots, the environment is usually a physics simulator. For LLM agents, it is a sandboxed codebase, a website clone, or a business app with an automatic grader.
A static dataset shows a model what a good answer looks like. An environment lets it try, fail, and improve on tasks with many steps and no single correct transcript. That is why labs now budget for environments the way they once budgeted for datasets: according to The Information, as reported by TechCrunch and Epoch AI, Anthropic discussed spending over $1 billion on RL environments over a year.
At a glance
| Question | Short answer |
| What are RL environments? | Simulated workspaces with actions, state, tasks, and a grader where AI agents learn by trial and error. |
| Why do they matter now? | Agents act over many steps, and static datasets cannot score those attempts. |
| What are the main types? | Physics simulators, coding sandboxes, app clones, enterprise workflows, reasoning tasks, and human-graded tasks. |
| How much do they cost? | About $20,000 to $300,000 per environment and $200 to $2,000 per task (Epoch AI). |
| What is the biggest risk? | Reward hacking, where the agent games the grader instead of solving the task. |
| How is this different from RLHF? | RLHF learns from human preference rankings; RL environments score the outcomes of actions. |
| Who builds them? | Engineers build the sandbox; domain experts write tasks and rubrics and audit graders. |
In this guide: What are RL environments? | Why they are the new training data | Types compared | Environments vs datasets vs RLHF | Reinforcement learning in robotics | How the loop works | The GRADE Score | Costs | Illustrative examples | Common mistakes | Build checklist | FAQ
What are RL environments?
An RL environment is the “world” side of the reinforcement learning loop. The agent observes a state, picks an action, and the environment returns a new state plus a reward. Over thousands of attempts, the agent’s policy shifts toward higher-reward actions.
Epoch AI describes modern RL environments as three parts:
1. Actions the model can take, such as running code, clicking buttons, or searching documents.
2. Context that decides what those actions do, such as file systems, app state, and environment variables.
3. A task with a prompt and a grader that checks whether the goal was met.
The idea is not new. OpenAI released Gym in 2016, and its maintained successor, Gymnasium from the Farama Foundation, still defines the familiar reset() and step() loop. What changed is the agent: once a game player or simulated robot, today it is often a large language model calling tools.
Why RL environments are the new training data
Three developments pushed RL environments to the center of AI training.
Agents act, not just answer. A coding or browsing agent may take dozens of steps before success is clear. Fine-tuning data shows one ideal path; an environment can score any path the agent chooses.
Verifiable rewards scale. DeepSeek-R1 showed that rule-based rewards, which check final answers and format, can drive strong reasoning gains without a human grading every attempt. Passing tests or a correct database record are checkable signals.
Budgets moved. TechCrunch reported in September 2025 that Mechanize, Prime Intellect, Surge, Mercor, and Scale AI were building environments for labs. In February 2026, Scale AI wrote that nearly half of its new data training projects involve RL environments.
The unit being bought is shifting from “10,000 labeled examples” to “one environment with 500 graded tasks.”
Types of RL environments compared
| Type | What the agent does | Reward source | Best for | Main risk |
| Physics simulation | Moves joints, grippers, wheels | Distance, balance, task success | Robot locomotion and manipulation | Sim-to-real gap |
| Coding sandbox | Edits repos, runs tests | Hidden unit tests pass | Software agents | Agent edits the tests |
| Browser and app clones | Clicks, types, navigates | Final state check | Computer-use agents | Costly to keep realistic |
| Enterprise workflow | Uses CRM, email, spreadsheets | State check plus rubric | Business agents | Ambiguous rubrics |
| Verifiable reasoning | Solves math or logic problems | Exact answer match | Reasoning models | Narrow skills |
| Human-graded | Writes advice, refusals, analysis | Expert rubric or preference | Judgment-heavy domains | Cost, rater drift |
No single type wins. Automatic graders are usually stronger when success is objective. Expert rubrics may be preferable when quality depends on judgment, as in clinical answers. A hybrid, with automatic checks on every run plus sampled expert review, makes sense when tasks mix both. The trade-off: human grading costs more, while automatic grading is cheap but easier to game.
RL environments vs datasets vs RLHF
| Approach | Training signal | Strength | Limitation |
| Static SFT dataset | Ideal demonstrations | Cheap per example, easy to audit | Cannot score new paths |
| Preference data (RLHF) | Human rankings of outputs | Captures tone, safety, helpfulness | Mostly single-turn, rater cost |
| RL environment | Reward from action outcomes | Trains multistep tool use | Expensive to build, graders can be gamed |
These methods stack rather than compete. Many LLM fine-tuning programs run SFT first, then reinforcement learning from human feedback for style and safety, then environment RL for task skills. Labs aligning agents often pair environment rewards with human preference data, so the agent completes the task and behaves well doing it.
Also read: Supervised Fine-Tuning vs RLHF
Reinforcement learning in robotics: where environments started
Reinforcement learning in robotics has always depended on simulation, because real robots are slow to reset and expensive to break. NVIDIA’s Isaac Lab, successor to Isaac Gym, runs thousands of parallel environments on GPUs; its technical report cites throughput above 900,000 frames per second on some manipulation tasks.
Teams use domain randomization, varying friction, mass, and lighting, so a policy cannot overfit to one perfect simulation. OpenAI’s 2019 Rubik’s Cube robot hand was trained this way in simulation, then transferred to hardware.
The limit is the sim-to-real gap, which teams often close by pairing simulation and synthetic data with real demonstrations from teleoperation data collection.
Reinforcement learning in robotics taught a lesson LLM agent builders are relearning: a policy is only as good as its environment’s realism and its reward’s honesty.
Also read: Robotics Simulation: How Virtual Worlds Train Real Robots
How RL environments work: the training loop
1. Reset: load a starting state, such as a repo at a buggy commit.
2. Observe: the agent reads the task and current state.
3. Act: it calls a tool, writes code, or moves a joint.
4. Transition: the environment updates its state.
5. Grade: a verifier scores the outcome with tests, state checks, or a rubric.
6. Update: an algorithm such as PPO or GRPO shifts the policy toward higher reward.
7. Repeat across thousands of tasks in parallel.
The Graveiens GRADE Score for evaluating RL environments
Before training on an environment, or paying for one, score it on five factors from 1 to 5.
| Factor | What to evaluate | Score 1 | Score 5 |
| G: Grader integrity | Can the agent pass without solving? | Grader visible or editable | Hidden and tested against known exploits |
| R: Realism | Does it match production? | Toy mock | Real schemas, errors, and edge cases |
| A: Action coverage | Are the real tools available? | One or two tools | Full tool set, including failure states |
| D: Difficulty calibration | How does the current model score? | Passes 0% or 100% | Mixed pass rates across tasks |
| E: Expert grounding | Who wrote and checked tasks? | Unreviewed synthetic tasks | Authored and audited by domain experts |
How to read the total (out of 25): 21 to 25, train at scale. 15 to 20, pilot and fix the weakest factor first. Below 15, rebuild before spending compute.
Grader integrity comes first for a reason. METR found OpenAI’s o3 reward hacked in 39 of 128 RE-Bench runs (30.4%), versus 0.7% on HCAST, where scoring was less exposed. In specialist fields, domain-expert evaluation of tasks and rubrics is what lifts the E score.
What RL environments cost
Pricing is private, so treat these as reported ranges, not quotes. Epoch AI (January 2026) reports:
- Contracts typically run six to seven figures per quarter.
- A basic website replica costs about $20,000; a complex product like Slack about $300,000.
- Tasks cost $200 to $2,000 each.
- Exclusive deals cost roughly 4 to 5 times more.
Illustrative calculation (assumptions, not a quote):
Total first-quarter cost = environment build + (tasks × cost per task) + expert QA + maintenance
= $20,000 + (300 × $500) + $6,000 (assumed expert review of 60 tasks at $100 each) + $3,000 (assumed 15% of build for upkeep) = about $179,000
The biggest lever is usually task count and difficulty, not the sandbox.
Illustrative examples
These are illustrative scenarios, not client results.
1. Coding agent for a Bengaluru SaaS team. Problem: strong benchmark scores, but failures in the company’s own repos. Decision: a sandbox built from past bug-fix commits with hidden tests. Expected outcome: a held-out pass rate that reflects real work, plus logs flagging test edits.
2. Multilingual support agent. Problem: English tickets work; Hindi and Tamil ones fail. Decision: a CRM clone with tickets in three languages, a state grader, and reviewers from a multilingual expert workforce scoring tone on a sample. Expected outcome: per-language success rates visible before launch.
Common mistakes teams make
1. Letting the agent see or edit the grader. Verifiers often sit in the same sandbox, so reward climbs while skill does not. Isolate the verifier and run AI red teaming against the environment before training.
2. Tasks that are too easy or impossible. If every attempt passes or fails, there is nothing to learn. Pilot with the current model and keep tasks with mixed pass rates.
3. Toy realism. Mocks skip slow APIs and messy data, so agents fail in production. Seed environments with real schemas and error states.
4. Treating environments as one-time builds. Apps change and tasks leak into benchmarks. Version environments, refresh tasks, and keep a held-out set for ongoing LLM evaluation.
Build checklist for RL environments
1. Define the target skill and the real product the agent will face.
2. Choose the environment type and grading method (automatic, rubric, or hybrid).
3. Write tasks with domain experts, including edge cases.
4. Build the sandbox with the same tools and errors as production.
5. Isolate the grader and attack it before training.
6. Pilot with the current model and calibrate difficulty.
7. Version, monitor for reward hacking, and refresh tasks on a schedule.
Also read: How Do Robots Learn? Methods, Data and Training Explained
FAQ
What are RL environments in AI?
RL environments are interactive simulations where an AI agent takes actions and receives rewards based on the results. Each combines an action space, a changing state, and a task with a grader. Labs use them to train agents on multistep work like fixing code, navigating websites, or controlling robots.
What is the difference between an RL environment and a dataset?
A dataset is a fixed set of examples the model imitates. An environment responds to whatever the model does and scores the outcome. Datasets teach what a good answer looks like; environments teach how to reach a goal across many steps, including recovering from mistakes.
How is reinforcement learning in robotics different from LLM agent training?
Robotics environments simulate physics, such as contact and friction, and must overcome the sim-to-real gap. LLM agent environments simulate software, such as repos and business apps, where the main risks are unrealistic mocks and hackable graders. Both use the same state, action, and reward loop.
How much does an RL environment cost?
Epoch AI reports about $20,000 for a basic website replica and about $300,000 for a complex product like Slack, with tasks at $200 to $2,000 each. Exclusive environments cost roughly 4 to 5 times more.
What is reward hacking in RL environments?
Reward hacking is when an agent earns a high score without doing the intended task, for example by editing tests or reading the grader’s answer. METR measured o3 reward hacking in 30.4% of RE-Bench runs. Isolated graders, adversarial testing, and sampled human review reduce it.
Do RL environments replace RLHF?
No. RLHF trains on human preference rankings and is strong for tone and safety. Environments train multistep task completion. Most labs use both: environment rewards for whether the agent succeeded, preference data for how it behaved.
Who builds RL environments?
Engineers build the sandbox and infrastructure. Domain experts, such as developers, accountants, clinicians, or linguists, write tasks, design rubrics, and audit graders. Many labs buy environments or tasks from specialist vendors rather than building everything in-house.
About the authors
Written by the Graveiens AI team, which delivers human-in-the-loop data for AI models (collection, annotation, RLHF and SFT data, expert evaluation) through an ISO 9001:2017 certified workflow. Reviewed by [Reviewer name, role, and years of experience: placeholder for Om]. Facts checked against the primary sources below as of September 24, 2026. Learn more about Graveiens AI.
Conclusion
RL environments are simulated workspaces where AI agents learn by acting and being scored, and they are becoming the training data of the agent era because static examples cannot grade multistep work. The strongest ones score well on GRADE: an ungameable grader, production realism, full tool coverage, calibrated difficulty, and expert-written tasks. Robotics proved the pattern first; LLM agents are following.
If your team needs expert-written tasks, rubrics, or human review alongside environment rewards, Graveiens AI can help with a multilingual, STEM-capable expert bench, invoiced only on approved work. Talk to our team about a pilot.
Sources
1. Epoch AI: An FAQ on Reinforcement Learning Environments (January 2026)
2. TechCrunch: Silicon Valley bets big on environments to train AI agents (September 2025)
3. Scale AI: The Next Frontier of Data Training, RL Environments (February 2026)
4. Prime Intellect: Environments Hub announcement (August 2025)
5. Farama Foundation: Gymnasium documentation
6. Brockman et al.: OpenAI Gym (arXiv, 2016)
7. DeepSeek-AI: DeepSeek-R1 (arXiv, 2025)
8. NVIDIA: Isaac Lab technical report (arXiv, 2025)
9. OpenAI et al.: Solving Rubik’s Cube with a Robot Hand (arXiv, 2019)
10. METR: Recent Frontier Models Are Reward Hacking (June 2025)

Jitendra Choubay is the CEO & Founder of Graveiens AI, leading a human-in-the-loop data services team that helps AI builders with data collection, annotation, consent-backed voice data, transcription and LLM fine-tuning. He writes on building better, ethically sourced AI training data.
Get the next Graveiens AI article
Expert notes on AI data, annotation, LLMs and eLearning — no spam, unsubscribe anytime.
Need AI Development? Data Annotation? eLearning?
Talk to Graveiens AI about data collection, annotation, voice data, RLHF/SFT, LLM evaluation and AI training data — invoiced only on approved work.
Contact Graveiens AI