Last updated: November 2026
Key takeaways
- EU AI Act training data requirements sit mainly in Article 10. They apply to high-risk AI systems and cover training, validation and testing data sets.
- After the Digital Omnibus on AI, Article 10 applies to Annex III high-risk systems from 2 December 2027 and to Annex I product-embedded systems from 2 August 2028.
- The provider owns the legal duty. Data vendors supply the evidence, such as consent records, provenance, QA reports and bias reviews.
- The old Article 10(5) rule on special-category data for bias detection now sits in a new Article 4a, with six strict conditions.
- GDPR still applies in parallel. An AI Act-ready dataset also needs a lawful basis and a clean consent trail.
Buyers and auditors now ask high-risk AI teams one hard question. Can you prove where your data came from, and that it fits the job? EU AI Act training data requirements turn that question into a legal duty.
Article 10 sets out how training, validation and testing data must be governed, checked for bias and documented. The Digital Omnibus on AI moved the dates, but the core duties stayed. This guide explains what Article 10 says, who owns each task, and the evidence pack your data vendor should hand over.
Not legal advice: this article is general information. Confirm how the AI Act applies to your system with qualified EU counsel.
Building a high-risk system for the EU market? Book a 20-minute scoping call and we will map the data evidence your project still needs.
What are the EU AI Act training data requirements?
EU AI Act training data requirements are the Article 10 rules for high-risk AI systems. Training, validation and testing data must follow documented governance practices and meet quality criteria. They must also reflect the setting where the system will run and be examined for bias. The provider must be able to show all of this.
In short: Article 10 does not ban any data source. It asks you to prove your data choices.
Which systems are covered?
Article 10 applies to high-risk AI systems. These include Annex III uses such as employment, education and access to essential services, plus AI built into products covered by Annex I. The Act reaches providers that place such systems on the EU market, wherever they are based.
For high-risk systems that do not train models, Article 10(6) applies the rules only to testing data sets.
When does Article 10 apply after the Digital Omnibus?
The Digital Omnibus on AI, Regulation (EU) 2026/1744, was published in the Official Journal on 24 July 2026. It entered into force on 27 July 2026. As of November 2026, the European Commission’s AI Act Service Desk timeline lists these dates:
- 2 August 2025: obligations for providers of general-purpose AI (GPAI) models apply.
- 2 August 2026: most rules apply, and enforcement starts for GPAI models, prohibitions, transparency rules and AI literacy.
- 2 December 2027: rules for high-risk AI systems in Annex III apply, including Article 10.
- 2 August 2028: rules for high-risk AI embedded in products covered by Annex I apply.
The delay buys time, not an exemption. Data collected now will often train the systems that must comply in late 2027, so build the evidence during collection.
What does Article 10 require, paragraph by paragraph?
Article 10 has four working parts. Paragraph 2 lists the governance practices your data must follow. Paragraph 3 sets quality criteria. Paragraph 4 asks data to match the real-world setting. A new Article 4a, added by the Digital Omnibus, covers sensitive data used for bias detection.
Article 10(2): data governance and management practices
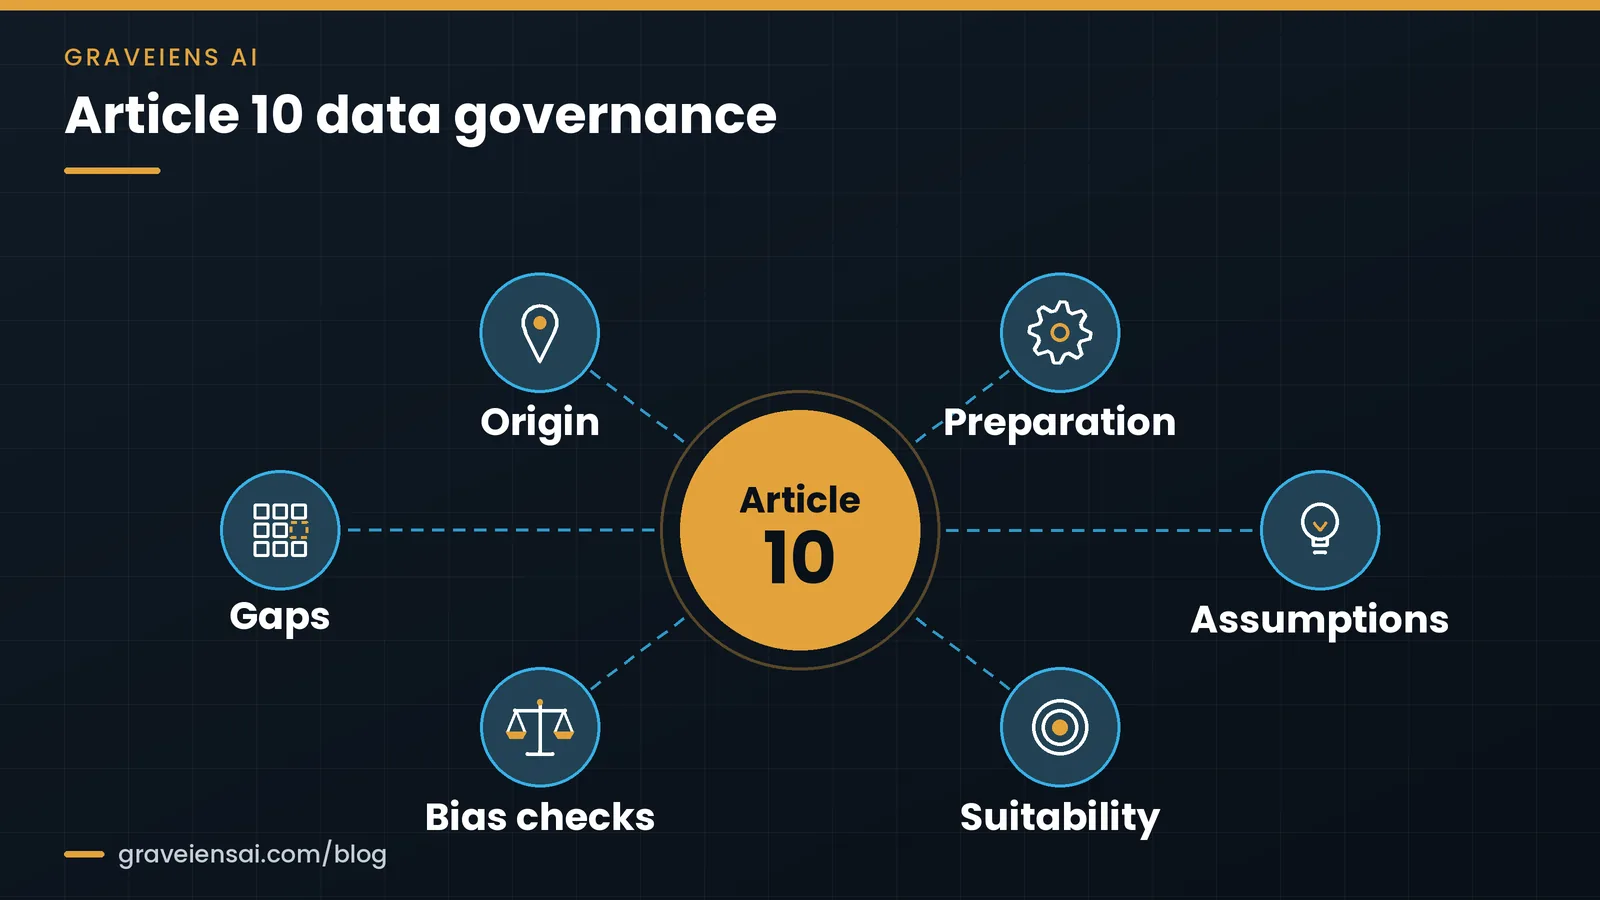
Article 10(2) says data sets “shall be subject to data governance and management practices appropriate for the intended purpose” of the system. It then lists what those practices must cover. Beyond the relevant design choices (point a), they fall into six evidence areas:
- Origin (point b): data collection processes and where the data came from. For personal data, record the original purpose of collection.
- Preparation (point c): annotation, labeling, cleaning, updating, enrichment and aggregation steps.
- Assumptions (point d): what the data is supposed to measure and represent.
- Suitability (point e): an assessment of the availability, quantity and suitability of the data sets needed.
- Bias checks (points f and g): examination for biases that could affect health, safety or fundamental rights, and measures to detect, prevent and mitigate them.
- Gaps (point h): data gaps or shortcomings that block compliance, and how you will address them.
Article 10(3): the quality criteria
Article 10(3) is the line most teams quote. Data sets “shall be relevant, sufficiently representative, and to the best extent possible, free of errors and complete in view of the intended purpose.” They must also have appropriate statistical properties for the people or groups the system will be used on.
Note the words “to the best extent possible.” The law does not demand perfect data. It demands a documented effort, judged against the intended purpose.
Article 10(4): context of use
Data sets must take into account the “geographical, contextual, behavioural or functional setting” where the system will be used. For a voice system, that can mean regional accents, phone-line audio and real background noise.
Former Article 10(5): now Article 4a
The Digital Omnibus deleted Article 10(5) and moved its content into a new Article 4a. Providers of high-risk systems may “exceptionally” process special categories of personal data to detect and correct bias. This is allowed only where strictly necessary and when six conditions are all met. Key ones:
- other data, including synthetic or anonymized data, cannot do the job;
- pseudonymization and strict access controls apply;
- the data is not transmitted to or accessed by other parties;
- the data is deleted once the bias is corrected or retention ends.
Article 4a applies in addition to GDPR, not instead of it.
The Article 10 Evidence Pack: a six-file checklist
Article 10 says what to govern, not which files to keep. We use a simple model with data buyers: the Article 10 Evidence Pack. It is six files every training, validation or test delivery should carry, each mapped to Article 10.
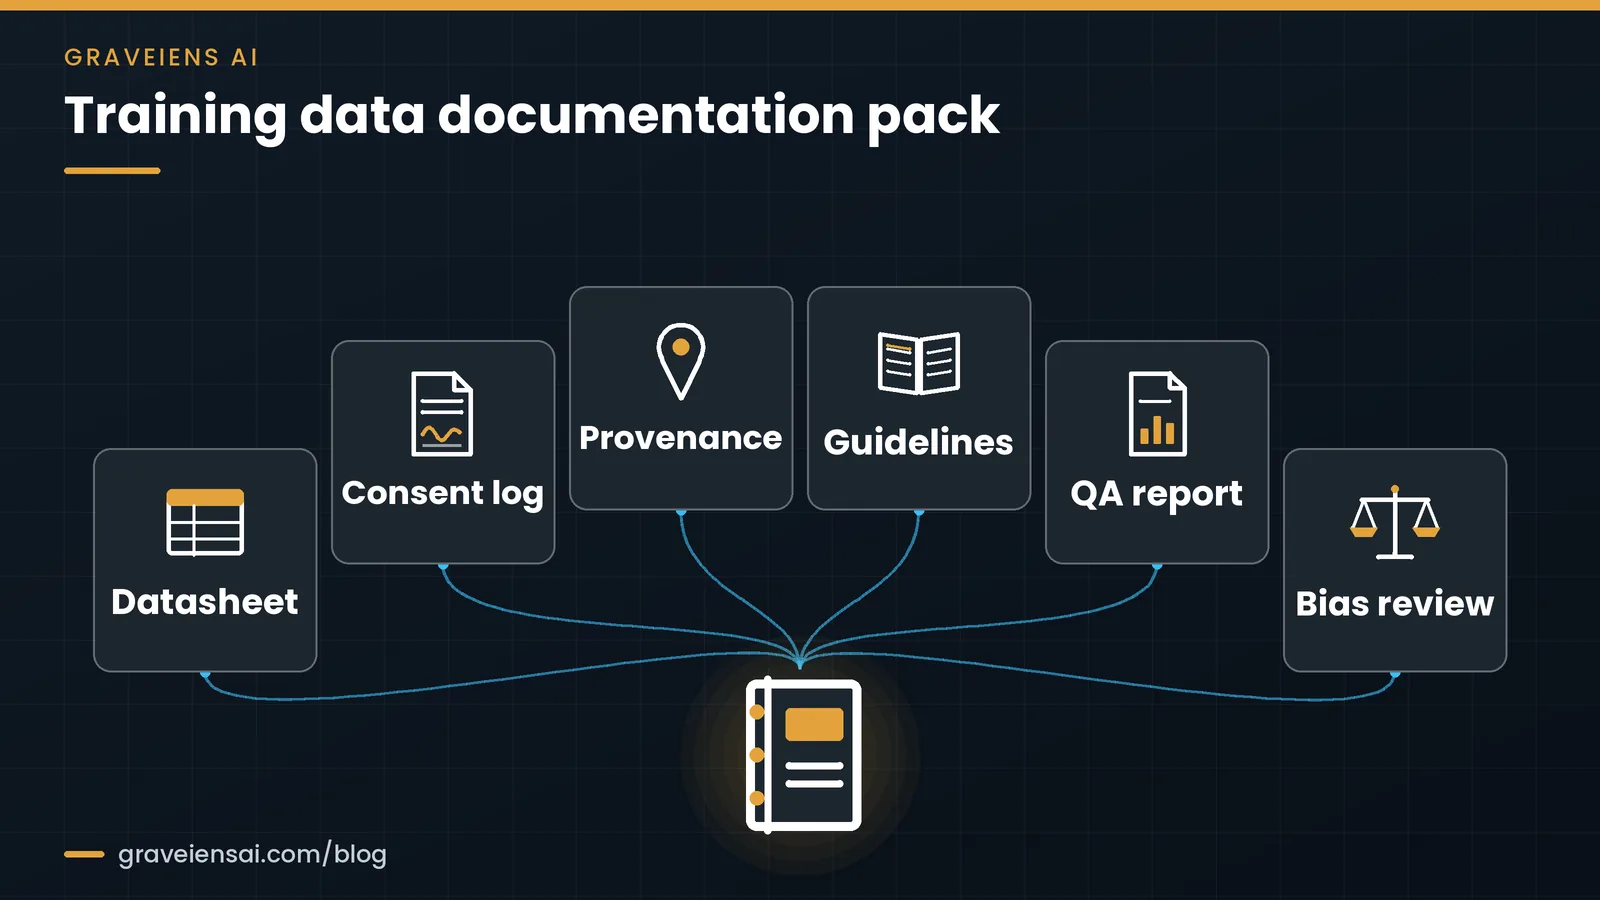
- Datasheet. What the data set contains, its intended purpose, volumes, splits and known limits. Supports design choices, assumptions and suitability (10(2)(a), (d), (e)).
- Consent log. Who agreed to what, when, and for which use, with withdrawal handling. Supports the personal-data purpose record in 10(2)(b) and your GDPR basis.
- Provenance record. Collection method, sources, dates, devices and any third-party inputs. Supports origin (10(2)(b)).
- Guidelines. Versioned annotation and labeling rules, with change logs. Supports preparation (10(2)©).
- QA report. Sampling method, error rates found, rework and acceptance results. Supports the “free of errors and complete” criterion (10(3)).
- Bias review. Coverage tables by relevant groups and settings, gaps found and actions taken. Supports bias checks, gaps and context (10(2)(f)-(h), 10(4)).
The provider folds these files into its technical documentation. If a file is missing, log it as a known gap under 10(2)(h), with a fix plan.
Want to see how consented, metadata-tagged data looks before you commit? Book a 20-minute scoping call, or scope a pilot billed only on approved files.
Who is responsible for training data: the provider or the data vendor?
The provider of the high-risk system carries the Article 10 duty. Supplying data does not make a vendor the provider. But Article 25(4) requires the provider and suppliers of tools, services, components or processes to agree in writing on the information and help the provider needs. In practice, the vendor supplies evidence.
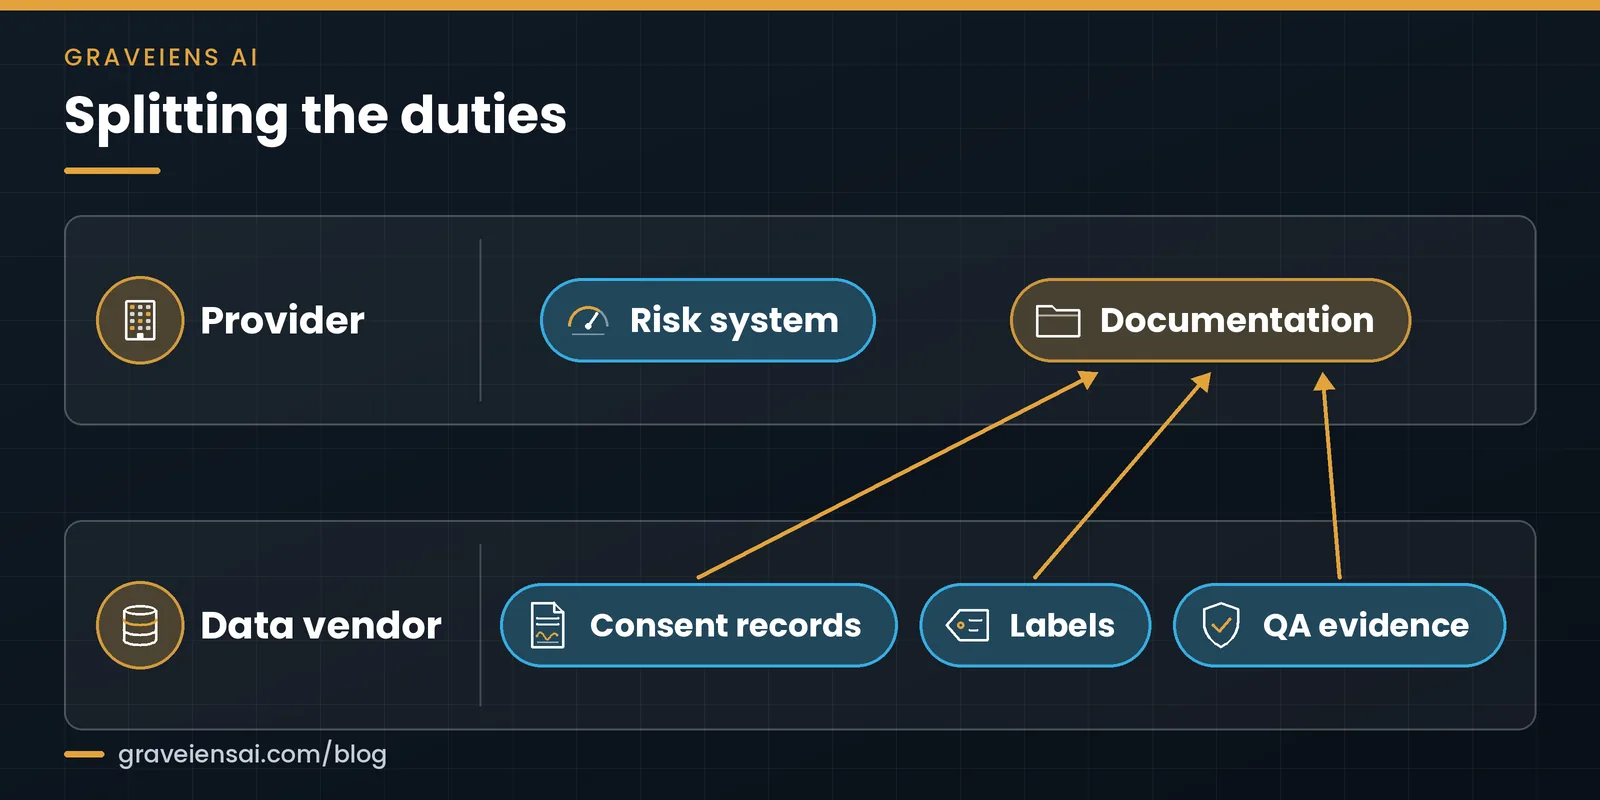
| Task | Provider | Data vendor |
|---|---|---|
| Intended purpose and data needs | Defines and signs off | Turns needs into a collection spec |
| Risk management (Article 9) | Owns the risk system | Flags data risks it sees |
| Collection and consent | Sets lawful basis and rules | Runs collection, keeps consent records |
| Annotation and labeling | Approves guidelines | Labels to versioned guidelines |
| Quality checks | Sets acceptance criteria | Runs QA, shares reports |
| Bias examination | Owns analysis and fixes | Supplies coverage data and metadata |
| Special-category data (Article 4a) | Processes only under the six conditions | Should not receive it unless counsel confirms |
| Technical documentation | Compiles and keeps it | Delivers the Evidence Pack files |
The Article 4a row matters most for planning. Because special-category data must not reach other parties, decide early where bias testing on sensitive attributes will happen. Often that is inside the provider’s own environment.
Write the split into your contract, naming each Evidence Pack file and its format. A risk management framework helps you connect data evidence to wider controls.
How does GDPR overlap with AI Act training data rules?
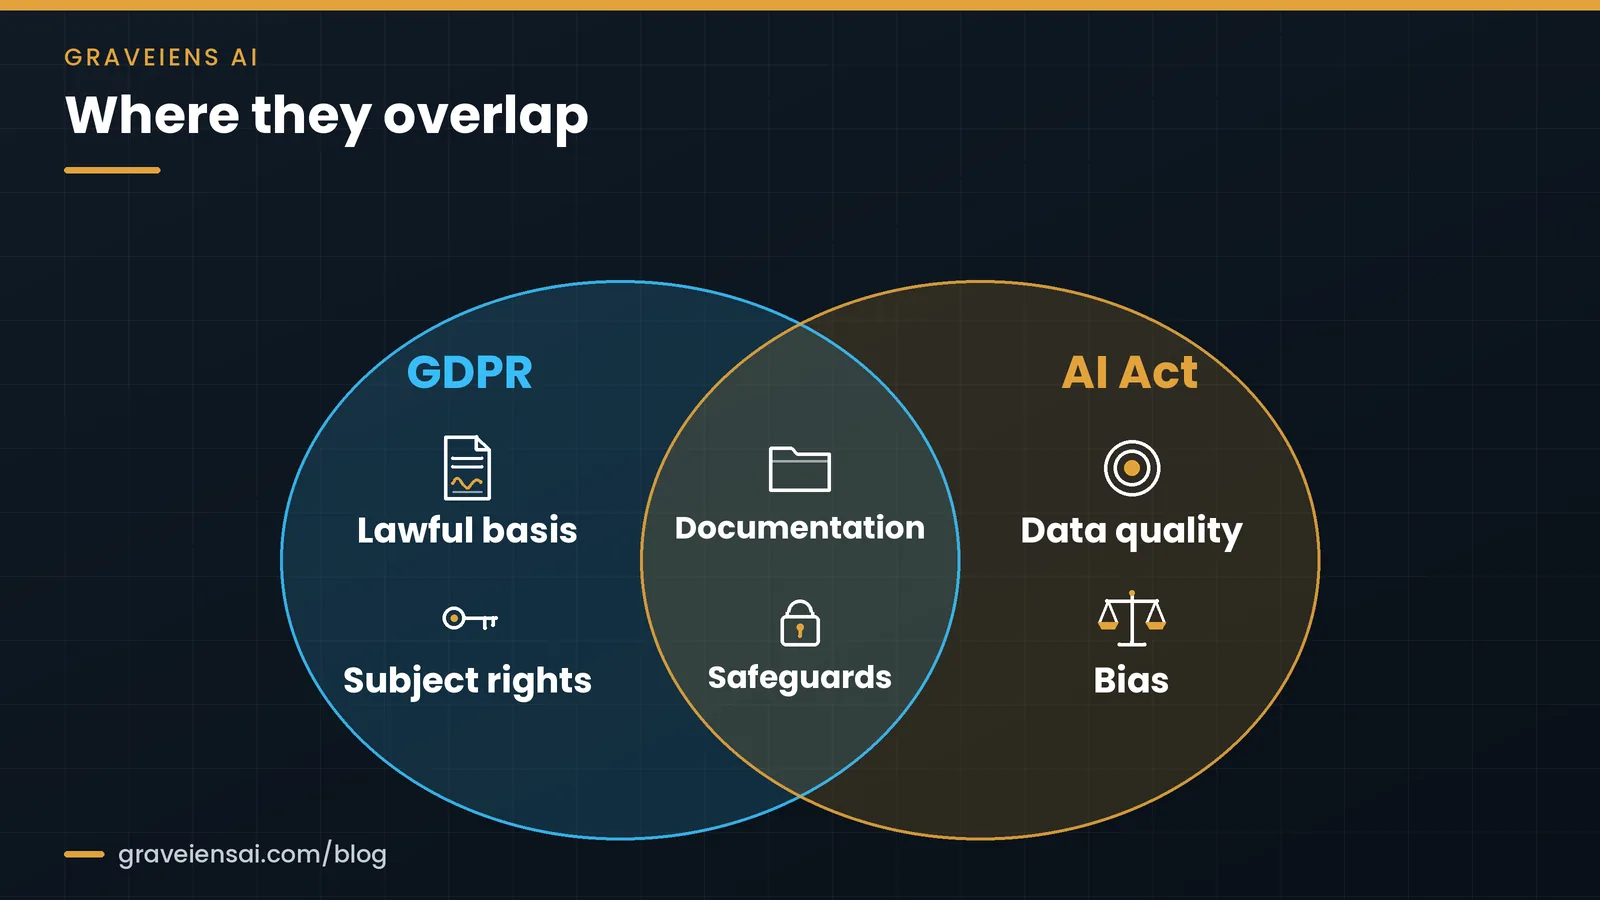
GDPR and the AI Act apply side by side. GDPR asks whether you may process personal data at all, and how you respect people’s rights. The AI Act asks whether the data is good enough and fair enough for a high-risk use. Documentation and special-category safeguards sit in both.
The European Data Protection Board (EDPB) adopted Opinion 28/2024 on AI models on 18 December 2024. It said legitimate interest can work as a legal basis only if the processing is strictly necessary and the balancing of rights is respected. It also warned that unlawfully processed training data could affect the lawfulness of a model’s deployment, unless the model is duly anonymized. So the consent trail is a deployment risk, not just paperwork.
For speech, image and video collection, explicit participant consent is usually the cleanest route. Our speaker consent form template shows the fields a consent record should capture.
What about general-purpose AI models?
GPAI providers face a different data duty. Article 53(1)(d) requires a public summary of the content used to train the model, using a template from the AI Office. The Commission published that template on 24 July 2025. GPAI obligations have applied since 2 August 2025.
As of November 2026, the Commission timeline shows GPAI enforcement started on 2 August 2026. Data suppliers to GPAI developers should expect questions on source types, collection periods and licensing, so keep them in the provenance record.
Common mistakes when evidencing Article 10
- Treating the Omnibus as a pause. Data collected today still feeds the systems due in 2027.
- Assuming the vendor carries compliance. The provider owns Article 10. Contracts should define what evidence the vendor must deliver.
- Losing the original purpose. Reused personal data without its original collection purpose is hard to defend under 10(2)(b).
- Unlogged guideline changes. If labeling rules changed mid-project without a log, your preparation record breaks.
- One-off bias checks. Bias examination should be repeated when data, labels or the intended purpose change.
- Sending sensitive attributes to vendors. Under Article 4a, special-category data used for bias work should not travel to other parties.
A quick refresher on what training data is, and how it differs from validation and test data, helps teams avoid mixing these splits.
How Graveiens AI approaches Article 10-ready data
Graveiens AI collects and prepares training data for AI teams in the US and EU. We do not give legal sign-off. We own the part a data partner can: consented data with the evidence attached.
- Explicit-consent collection. Our data collection workflow runs participant onboarding, recording and capture management, metadata tagging and QA, with consent captured up front.
- Versioned labeling. Our data annotation teams work to written guidelines with logged changes.
- Independent checks. Data validation adds a second QA layer and a report you can file.
- Coverage. We work in 25+ languages, including Indian and European languages such as Italian.
- Process discipline. Graveiens AI is ISO 9001 certified and bills on approved deliverables.
Frequently asked questions
Does the EU AI Act apply to US companies?
Yes, if they place AI systems or general-purpose AI models on the EU market, or their system’s output is used in the EU. Where the company is based does not decide scope. A US provider selling a high-risk hiring or credit tool to EU customers must meet Article 10 for its training, validation and testing data.
When do Article 10 requirements start to apply?
After the Digital Omnibus on AI, Article 10 applies to Annex III high-risk systems from 2 December 2027. For high-risk AI embedded in products covered by Annex I, the date is 2 August 2028. Because training data is collected well before launch, most teams should build their evidence during collection, not after it.
Does Article 10 apply to all AI systems?
No. Article 10 applies to high-risk AI systems only. Minimal-risk tools, such as spam filters, are not bound by it. Even so, many buyers now ask for the same evidence in contracts. For high-risk systems that do not train models, Article 10(6) limits the rules to testing data sets.
Can we use sensitive personal data to test for bias?
Possibly, under Article 4a, which replaced Article 10(5). Providers may exceptionally process special categories of personal data where strictly necessary for bias detection and correction. Six conditions apply, including no workable alternative such as synthetic data, strict access controls, no sharing with other parties, and deletion once the bias is fixed. GDPR still applies too.
Is the data vendor liable under Article 10?
The provider of the high-risk system carries the Article 10 duty, not the data vendor. However, Article 25(4) requires providers and their suppliers to agree in writing on the information and help needed for compliance. In practice, vendors should deliver consent records, provenance, labeling guidelines, QA reports and coverage data with every delivery.
What is the GPAI training data summary template?
It is the AI Office template that general-purpose AI model providers must use to publish a summary of their training content under Article 53(1)(d). The Commission published it on 24 July 2025. It asks for information about the provider, the model and the main data sources used. It is separate from Article 10, which covers high-risk systems.
Get Article 10-ready training data
Start small and judge the files yourself. Book a 20-minute scoping call or ask us for the Article 10 Evidence Pack checklist. Pilots are billed only on approved files.
Sources
- EUR-Lex: AI Act (Regulation (EU) 2024/1689), consolidated text as at 27 July 2026
- European Commission AI Act Service Desk: implementation timeline
- European Commission: GPAI training content summary template (24 July 2025)
- EDPB: Opinion 28/2024 on AI models (18 December 2024)
About the author
Graveiens AI Editorial Team. Our editorial team writes about AI training data, speech data and data compliance for AI builders in the US and EU. The team works alongside our data collection, annotation and QA leads, so each guide reflects how real projects run.

Jitendra Choubay is the CEO & Founder of Graveiens AI, leading a human-in-the-loop data services team that helps AI builders with data collection, annotation, consent-backed voice data, transcription and LLM fine-tuning. He writes on building better, ethically sourced AI training data.
Get the next Graveiens AI article
Expert notes on AI data, annotation, LLMs and eLearning — no spam, unsubscribe anytime.
Need AI Development? Data Annotation? eLearning?
Talk to Graveiens AI about data collection, annotation, voice data, RLHF/SFT, LLM evaluation and AI training data — invoiced only on approved work.
Contact Graveiens AI